> ## Documentation Index
> Fetch the complete documentation index at: https://docs.pullfrog.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Models
Pullfrog model names are rolling aliases — like a `latest` tag on npm. "Claude Opus" resolves to a concrete version at runtime (`anthropic/claude-opus-5`), and when a new generation ships we bump it. Your configuration doesn't change.
## Selecting a model
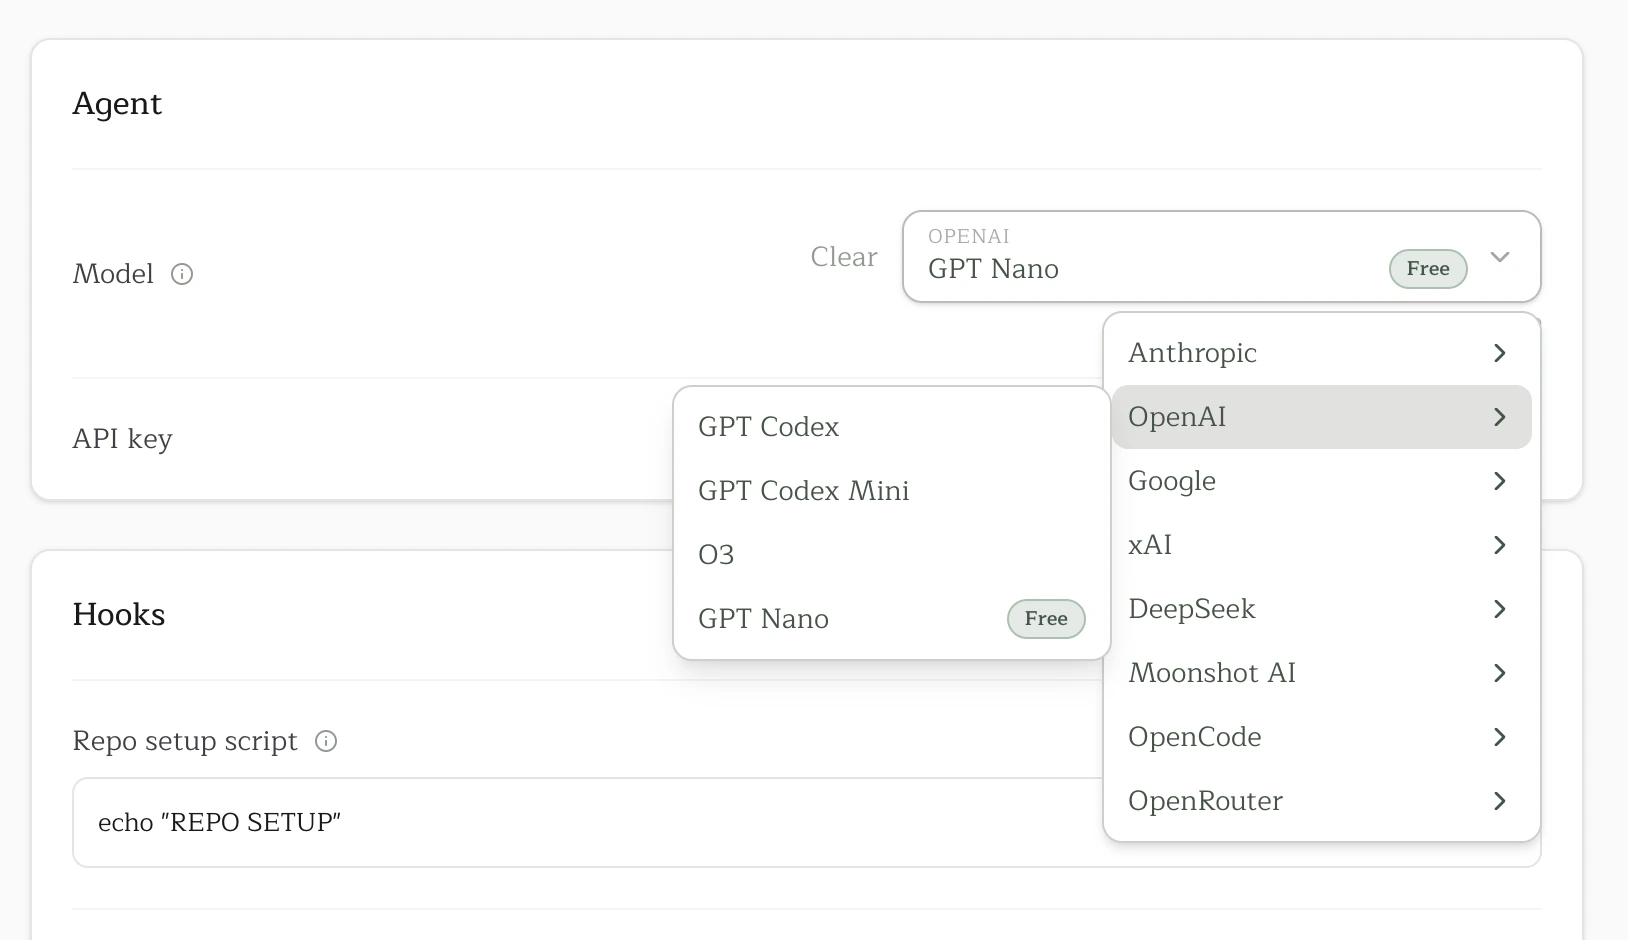
Pick one under **Agent > Model** in the [console](https://pullfrog.com/console). The **API key** row names the secret that model needs; store it in the console or in your workflow `env:` — see [BYOK](/keys). Set an org-wide default from the org console, which every repo inherits until it picks its own.
 ### Smart
Under **Provider**, pick the provider whose key you store, then set **Model selection** to **Smart** or **Manual**. **Manual** pins one model from that provider's menu and sets its reasoning effort. **Smart** picks the model for each pull request: Pullfrog reads the diff and runs a small change that can be checked line by line on a cheaper model, and a change that reaches across many files on the frontier one, using that provider's whole ladder — Luna, Terra, Sol and Astra on OpenAI; Haiku, Sonnet and Opus on Anthropic; Flash and Pro on Google. Issue labeling and other small chores take the cheapest rung; mentions and fixes the middle one. The **Model** row under Smart lists the ladder and what each model takes. The scoring runs on Pullfrog's own model, whatever credential the provider is configured with. Beneath the ladder, **Custom instructions** takes standing guidance for that choice — which paths or kinds of change deserve the top model or more reasoning effort, which can stay on the cheapest rung at low effort — written against the provider you picked, so changing the provider clears it. Lockfiles, snapshots and generated files are already left out when a diff is weighed, so they need no mention; guidance for the review itself belongs in Standing instructions, not here. The **Provider** card shows the credential that pays for the runs, or the way to set one up.
Smart is part of [Pro](/billing); outside it the tab carries a lock, and opening it explains how Smart works and where to upgrade. On [Pullfrog Router](/billing) it picks between DeepSeek Flash, GPT Luna, GPT Sol and Claude Opus, and stays on DeepSeek Flash until a card is on file.
**Reasoning effort** sits under a pinned model and offers exactly the levels that model publishes; Smart sets it per run. Per run, use the [`--effort` flag](/flags#effort).
Models marked **Free** cost nothing per token, but OpenCode Zen still authenticates the request — `OPENCODE_API_KEY` is required. See [free models](/keys#free-models).
On [Pullfrog Router](/billing) without a card on file, a positive balance runs DeepSeek Flash and the other models are locked, so a credit balance can't be spent on a premium model; with no balance at all, runs stop until you add a card or top up. Adding a card unlocks every model. [Free models](/keys#free-models) and any model you hold a [Pullfrog-stored key](/keys) for are exempt. BYOK is never gated.
### Pullfrog for OSS
Repos in [Pullfrog for OSS](https://pullfrog.com/for-oss) have their model costs covered by us, so the picker offers the set we fund:
| Model | Notes |
| ---------------------- | ---------------------------------------------------------------------- |
| **DeepSeek Flash** | Recommended, and the default |
| GPT Luna | OpenAI's cost-efficient tier |
| MiniMax M2 | |
| Muse Spark Contributor | Meta's discounted tier — Meta may train on the prompts and completions |
Anything outside this set falls back to the default, and the PR footer says so — unless you've stored that provider's key **with Pullfrog**, in which case the run uses your key and your pick. A key that lives only in GitHub Actions secrets doesn't opt you out, because the server can't see it when it decides. Same rule for a per-run [`--model` flag](/flags).
## Model resolution
When a run starts, Pullfrog picks a model in this order:
1. **`model` action input** — your workflow file, or the console. The recommended way.
2. **Auto-select** — Pullfrog asks OpenCode which models your keys can reach and takes the best curated match, preferring each provider's top tier.
3. **Provider default** — OpenCode's own pick, if nothing matched.
Specifiers use the [models.dev](https://models.dev) format (`anthropic/claude-opus-5`); Pullfrog's aliases map onto them.
The model also decides which agent runs it: an Anthropic model with Anthropic credentials runs on Claude Code, and everything else runs on OpenCode. Organizations opted in to the experimental [Codex CLI](https://developers.openai.com/codex/cli) agent run OpenAI models on Codex instead, when a [Codex subscription](/codex-auth) or an `OPENAI_API_KEY` is present. Runs billed through [Pullfrog Router](/billing#pullfrog-router) or the OSS program always use OpenCode.
### Supported providers
| Provider | API key env var |
| ------------------------------------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------- |
| Anthropic | `ANTHROPIC_API_KEY` (or a [Claude subscription](/claude-auth)) |
| OpenAI | `OPENAI_API_KEY` (or a [Codex subscription](/codex-auth)) |
| Google | `GOOGLE_GENERATIVE_AI_API_KEY` or `GEMINI_API_KEY` |
| xAI | `XAI_API_KEY` (or a [Grok subscription](/grok-auth)) |
| DeepSeek | `DEEPSEEK_API_KEY` |
| Moonshot AI | `MOONSHOT_API_KEY` |
| Meta | `META_MODEL_API_KEY` — the [Meta Model API](https://dev.meta.ai), for Muse Spark |
| [Kimi Code](/kimi-code) | `KIMI_API_KEY` — a Kimi membership rather than a Moonshot API balance |
| OpenCode | `OPENCODE_API_KEY` — one key for [Zen and Go](#opencode-zen-and-opencode-go), and required for the free Zen models too |
| OpenRouter | `OPENROUTER_API_KEY` |
| Vercel AI Gateway | `AI_GATEWAY_API_KEY` |
| [Amazon Bedrock](/bedrock) | `AWS_BEARER_TOKEN_BEDROCK` (or `AWS_ACCESS_KEY_ID` + `AWS_SECRET_ACCESS_KEY`) + `AWS_REGION` + `BEDROCK_MODEL_ID` |
| [Google Vertex AI](/vertex) | `VERTEX_SERVICE_ACCOUNT_JSON` + `GOOGLE_CLOUD_PROJECT` + `VERTEX_LOCATION` + `VERTEX_MODEL_ID` |
| [Azure OpenAI](/azure) | `AZURE_RESOURCE_NAME` + `AZURE_API_KEY` + `AZURE_DEPLOYMENT` + `AZURE_CONTEXT` + `AZURE_MAX_OUTPUT` |
| [Custom › OpenAI-compatible](/openai-compatible) | `OPENAI_COMPATIBLE_BASE_URL` + `OPENAI_COMPATIBLE_API_KEY` + `OPENAI_COMPATIBLE_MODEL` + `OPENAI_COMPATIBLE_CONTEXT` + `OPENAI_COMPATIBLE_MAX_OUTPUT` |
## Custom providers
The table above is what the console has a card for. It is not the limit of what runs.
Pullfrog runs models through [OpenCode](https://github.com/anomalyco/opencode), which carries the whole [models.dev](https://models.dev) catalog. Any provider there — Groq, Mistral, Cerebras, Together, Fireworks — switches on the moment its API key is in the run's environment. Nothing to enable, nothing to wait on us for.
This is BYOK. Set **Model access** to BYOK on the Billing card first — on [Router](/billing) billing the server hands the run a Router credential before it starts, and a key that lives only in GitHub Actions secrets is invisible to the server, so it can't know to step aside.
**1. Add the key** as a GitHub Actions secret, under the exact name that provider's [models.dev](https://models.dev) page declares.
**2. Map it in, and name the model.** The specifier must be one models.dev lists — the run checks it against the provider's catalog before starting. Non-secret settings some providers want (a region, an endpoint) go straight in `env:`.
```yaml theme={null}
- name: Run agent
uses: pullfrog/pullfrog@v0
with:
prompt: ${{ inputs.prompt }}
model: groq/llama-3.3-70b-versatile
env:
GROQ_API_KEY: ${{ secrets.GROQ_API_KEY }}
```
**3. Set the console model to Custom.** A model stored in the console beats the workflow's `model` input, so pick **Custom (set in workflow)** — or **Inherit from org** if your org has a default. The job log confirms it took:
```
» "groq/llama-3.3-70b-versatile" is not a curated alias — passing through as a raw model specifier
```
Use [OpenAI-compatible endpoints](/openai-compatible) instead when your provider isn't in the catalog, when you front several behind one gateway, or when you need a model ID the catalog doesn't carry.
## Routers
OpenRouter, OpenCode Zen, OpenCode Go, and Vercel AI Gateway are providers like any other, with their own aliases (OpenRouter's "Claude Opus" → `openrouter/~anthropic/claude-opus-latest`). To pin an exact version instead of the rolling alias, set the `model` input to the full specifier:
```yaml theme={null}
with:
model: openrouter/anthropic/claude-sonnet-5
env:
OPENROUTER_API_KEY: ${{ secrets.OPENROUTER_API_KEY }}
```
### OpenCode Zen and OpenCode Go
[Zen](https://opencode.ai/zen) and [Go](https://opencode.ai/go) are two OpenCode plans behind one credential. Store `OPENCODE_API_KEY` once and both groups appear in the picker.
| Plan | Billing | Models |
| ---------------- | ------------------------ | -------------------------------------------------------------------- |
| **OpenCode Zen** | Pay as you go | Claude, GPT, Gemini, Grok, Kimi, MiniMax, GLM, MiMo, Muse Spark |
| **OpenCode Go** | \$10/month, capped usage | GLM, Qwen, Kimi, MiniMax, MiMo, LongCat, Hy3, plus Grok and GPT Luna |
Most of the Go catalog is not served on Zen at all, so the two groups are not two spellings of the same menu.
DeepSeek and Muse Spark are missing from the Go menu on purpose. OpenCode gates them on a workspace opt-in that is off by default — China hosting for DeepSeek, data collection for Muse Spark — so a run refuses with a link to the setting. Turn it on at your OpenCode workspace and they run by full specifier, as below. DeepSeek needs no opt-in on any other route.
### Models the picker does not carry
The picker is a curated menu. Any other model either endpoint serves runs by its full [models.dev](https://models.dev) specifier:
```yaml theme={null}
with:
model: opencode-go/mimo-v2-omni
env:
OPENCODE_API_KEY: ${{ secrets.OPENCODE_API_KEY }}
```
Set the console model to **Custom (set in workflow)** so a stored pick does not beat the workflow input — the same rule as [custom providers](#custom-providers).